

Learning how to make important website content easier to crawl is an essential part of technical SEO and a useful foundation for improving your website’s search visibility. Even if you publish high-quality articles, guides, and service pages, search engines may struggle to discover them when your website has poor navigation, broken links, or technical restrictions.
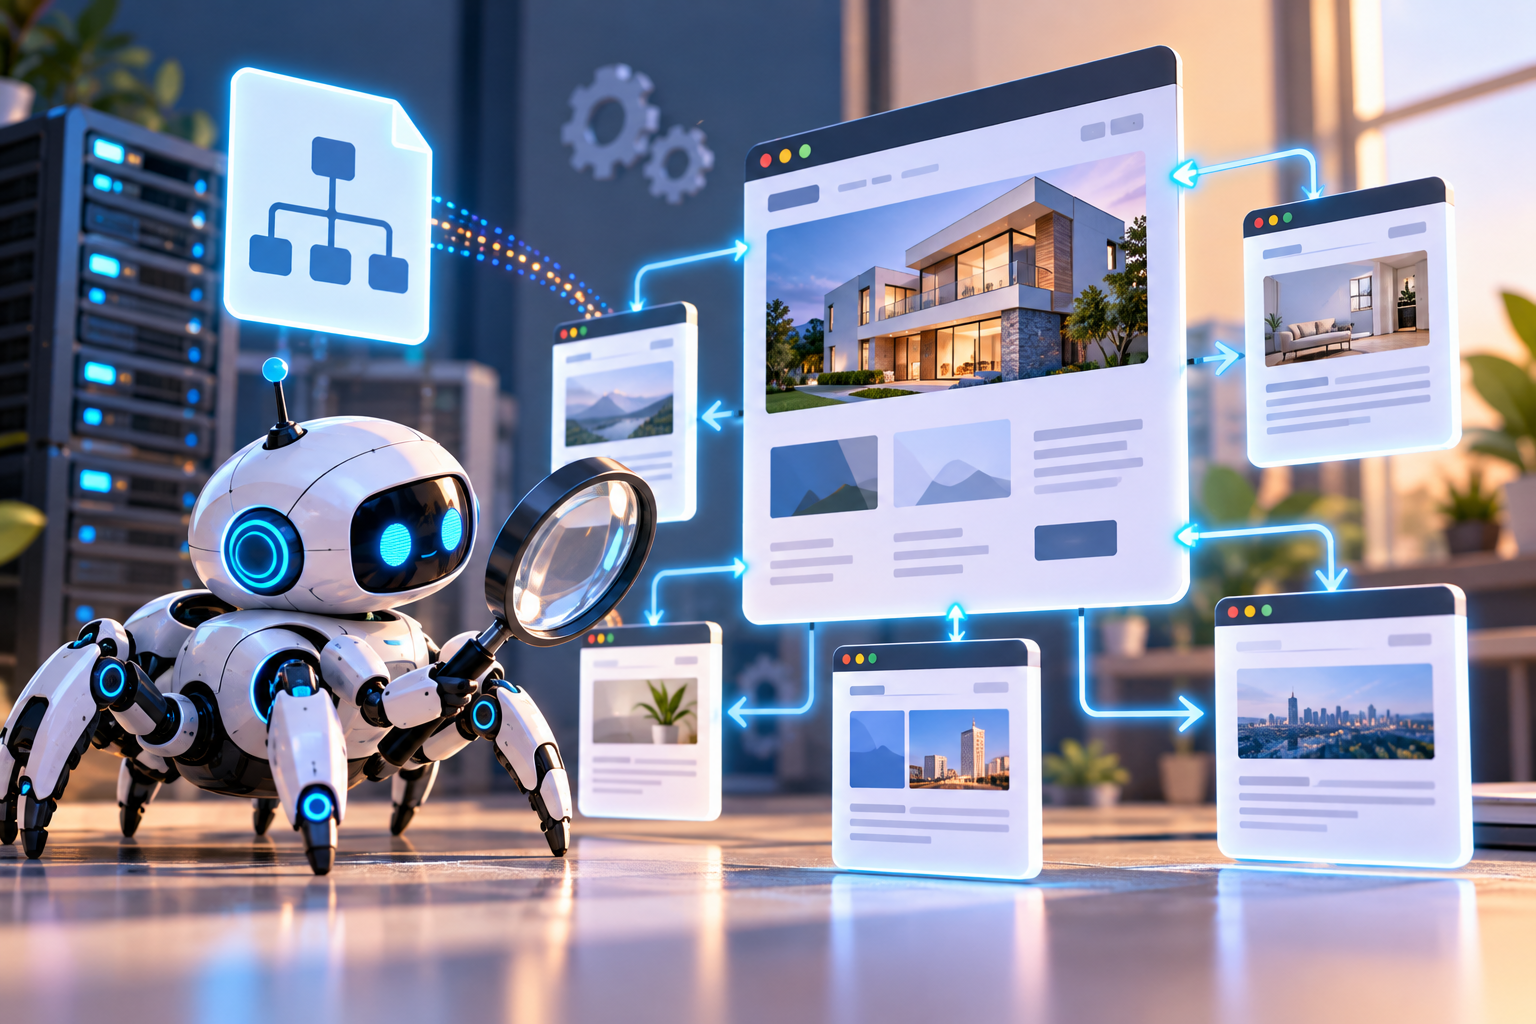
Crawling is the process through which search engine bots discover URLs and access their content. It is an important step before a page can be evaluated for indexing and potentially shown in search results.
For website owners, the goal is simple: help search engines discover the pages that matter, access their content, and understand how those pages relate to one another.
Good crawlability also supports a well-organised website that is easier for visitors to navigate. While making content crawlable does not guarantee rankings or AI citations, it gives your pages a stronger technical foundation.
In this guide, you will learn how to improve website crawlability using practical steps that beginners and small business owners can follow.
1. Understand Which Pages Matter Most
Before changing your website, identify the pages you want search engines to discover.
These may include:
- Important service pages
- Product pages
- Main category pages
- Valuable blog posts
- Helpful guides and tutorials
- Location pages for local businesses
- Core landing pages
Not every URL needs to be crawled or indexed. For example, duplicate pages, internal search results, and certain account or checkout pages may not need to appear in search results.
Create a simple list of your most important URLs and check whether each page is accessible, linked from relevant pages, and included in your intended site structure.
Prioritising important pages helps you focus your efforts instead of trying to make every URL equally prominent.
2. Build a Clear Internal Linking Structure
Internal links connect one page on your website to another page on the same website.
They help visitors navigate your content and give search engines additional paths for discovering URLs.
For example, an article about technical SEO can link to a related guide about website indexing, while a broader SEO guide can link to detailed articles about crawlability, XML sitemaps, and internal linking.
Use descriptive anchor text that tells readers what they will find when they follow a link.
Avoid leaving important pages isolated with no links pointing to them. These are sometimes called orphan pages.
How to improve internal linking
- Link from relevant, established pages to important new content.
- Connect related articles within the same topic cluster.
- Use descriptive anchor text.
- Add useful links in navigation menus where appropriate.
- Check for broken internal links.
- Avoid adding irrelevant links simply to increase their number.
A clear internal linking structure can make important content easier to discover without requiring every page to sit directly on the homepage.
3. Create and Maintain an XML Sitemap
An XML sitemap lists URLs that you want search engines to discover and consider for crawling.
It can be particularly useful for large websites, new websites, or websites with pages that are not easily discovered through internal links.
A useful XML sitemap should generally contain canonical URLs that you want search engines to index.
Avoid including URLs that are blocked, redirected, duplicated, or intentionally marked as noindex unless there is a specific reason and you understand the implications.
How to check your sitemap
- Open your website’s XML sitemap. A common location is
yourdomain.com/sitemap.xml, although the exact location can vary. - Check that important URLs are included.
- Confirm that the URLs use the correct domain and preferred HTTPS version.
- Remove outdated or irrelevant entries through your sitemap generator or CMS settings.
- Submit the sitemap through Google Search Console and monitor any reported issues.
A sitemap is a discovery aid, not a guarantee that every listed page will be crawled or indexed.
4. Check Your Robots.txt File Carefully
The robots.txt file gives compatible crawlers instructions about which paths they may access.
A rule that blocks an important directory can prevent a search engine from crawling valuable pages or resources.
For example, a website might accidentally block a folder containing blog posts or important product information.
What to check
- Confirm that important content directories are not accidentally blocked.
- Review any rules added during development.
- Check whether CSS or JavaScript resources needed to understand the page are restricted.
- Verify that the sitemap location is included when appropriate.
- Test relevant URLs using available search engine tools.
Be careful when changing robots.txt. A rule intended to stop unimportant pages from being crawled can accidentally restrict a large section of your website.
Also remember that robots.txt is not a reliable method for keeping private information secure. Use proper authentication and access controls for confidential content.
5. Fix Broken Links and Redirect Chains
Broken links can interrupt navigation and prevent crawlers from reaching the intended destination through that path.
Redirects are useful when pages move, URLs change, or content is consolidated. However, unnecessary chains of redirects can make crawling less efficient and complicate website maintenance.
For example, a link might lead from one old URL to another redirected URL before finally reaching the current page.
How to fix these issues
- Find internal links that return errors.
- Update links that point to outdated URLs.
- Redirect permanently moved pages to the most relevant replacement.
- Avoid redirecting multiple times when a direct destination is available.
- Remove links to pages that no longer exist when there is no suitable replacement.
- Check that important pages return the expected HTTP status.
A normal page should generally return a successful response, while a permanently moved page may use a 301 redirect. Do not redirect every removed page to the homepage if that does not serve the visitor’s intent.
6. Use Clean and Consistent URLs
A clear URL structure helps users understand a page’s location and makes website management easier.
For example:
example.com/seo/website-crawlability/
is generally easier to interpret than a URL filled with unnecessary parameters and confusing identifiers.
However, URL length alone is not a reliable measure of crawlability. A technically accessible URL can still be crawled even if it is not especially short.
Focus on consistency rather than changing URLs simply to make them look cleaner.
Good URL practices
- Use a logical folder structure where appropriate.
- Avoid unnecessary URL parameters.
- Keep canonical and internal link versions consistent.
- Use the preferred HTTPS version.
- Avoid creating multiple URLs for the same content without a clear reason.
- Redirect old URLs appropriately when making necessary changes.
Changing established URLs can affect traffic and links, so plan redirects carefully before making large structural changes.
7. Manage Duplicate Content and Canonical URLs
Websites sometimes expose similar or identical content through multiple URLs.
This can happen because of tracking parameters, sorting options, session identifiers, printer-friendly versions, or inconsistent URL formats.
Duplicate URLs can make it harder for search engines to determine which version should be treated as the primary page.
Canonical tags help indicate the preferred version of substantially similar pages.
For example, if a product page is accessible through several URL variations, a correctly implemented canonical tag may identify the main version.
What you should do
- Identify important pages with multiple URL variations.
- Choose a preferred URL for each page where appropriate.
- Use consistent internal links to that preferred version.
- Implement canonical tags correctly.
- Avoid using canonical tags to point unrelated pages to one another.
- Check whether parameter-based URLs are creating unnecessary duplicates.
Canonical tags are signals, not absolute commands. Search engines may select a different canonical URL if other signals suggest that another version is more appropriate.
8. Make Important Content Available in Readable HTML
Search engines can process JavaScript, but some implementations make content more difficult to discover or render correctly.
If essential text appears only after a complicated interaction or depends on a failed script, a crawler may not access it as intended.
For example, a service page may appear complete in a browser but deliver very little meaningful content in its initial HTML.
How to improve content accessibility
- Ensure important page text is available to search systems.
- Use standard HTML links for important navigation.
- Avoid requiring a click or hover interaction just to reveal essential information.
- Check pages that depend heavily on JavaScript.
- Test whether important content appears after rendering.
- Keep primary content accessible on mobile devices.
You do not need to avoid JavaScript altogether. The goal is to ensure that your site’s essential content and links can be discovered and processed reliably.
9. Improve Website Navigation
A clear navigation system helps visitors and crawlers understand the relationship between major sections of your website.
For example, a digital marketing website might organise its content into SEO, social media marketing, AI marketing, and AEO categories.
Each category page can link to its most useful articles, helping users explore related information.
Navigation improvements to consider
- Use clear category names.
- Link important pages from relevant navigation areas.
- Avoid unnecessarily deep page hierarchies.
- Create useful category or topic pages.
- Ensure navigation works on mobile.
- Avoid relying exclusively on complex interactive menus.
There is no universal rule that every page must be within a specific number of clicks from the homepage. Instead, make important pages easy to find through a sensible and consistent structure.
10. Monitor Crawl Errors in Google Search Console
Google Search Console provides useful information about how Google discovers and processes website URLs.
Its Page Indexing report can help you investigate why certain pages are not indexed. URL Inspection can provide additional information about an individual URL, including Google’s last crawl information where available.
Remember that not every page excluded from indexing has a technical problem. Some pages may be duplicates, redirects, or intentionally excluded.
A practical checking process
- Verify your website in Google Search Console.
- Review the Page Indexing report.
- Look for important pages that are unexpectedly excluded.
- Inspect selected URLs individually.
- Check for server errors, redirect issues, or access restrictions.
- Fix the underlying problem and request recrawling when appropriate.
Requesting indexing does not guarantee immediate crawling or inclusion in search results.
11. Check Your Website’s Response Codes
HTTP status codes help crawlers understand what happened when they requested a URL.
Some common responses include:
| Status code | Meaning | What to check |
|---|---|---|
| 200 | The request succeeded | Confirm the page contains the intended content |
| 301 | Permanent redirect | Ensure the destination is relevant |
| 302 | Temporary redirect | Confirm the temporary behaviour is intentional |
| 404 | Page not found | Repair important broken links or redirect where appropriate |
| 5xx | Server error | Investigate hosting or server problems |
If important pages repeatedly return server errors, search engines may have difficulty crawling them reliably.
Use a website crawler, browser developer tools, server logs, or other appropriate diagnostics to investigate unexpected responses.
Do not try to eliminate every 404 response. Some URLs are legitimately unavailable, and returning a proper 404 can be the correct behaviour.
12. Avoid Creating Too Many Low-Value URLs
Some websites generate huge numbers of URLs through filters, sorting options, calendars, search results, and combinations of parameters.
For example, an online store may create a separate URL for every combination of colour, size, sorting order, and filter selection.
Many of these pages may offer little unique value.
When a website creates too many low-value URLs, search engines may spend time revisiting pages that are less important while useful content receives less attention.
How to manage URL growth
- Review which parameter combinations create URLs.
- Keep useful category and product pages accessible.
- Prevent unnecessary internal links to endless filter combinations.
- Use appropriate canonicalisation where suitable.
- Restrict crawling of unimportant URL spaces when justified.
- Avoid blocking URLs before understanding their indexing and canonicalisation role.
Do not automatically block all filtered pages. Some filter combinations may be valuable landing pages if they serve real search demand and contain useful content.
13. Make Sure Important Pages Are Not Accidentally Set to Noindex
A noindex directive tells compatible search engines not to include a page in their search results.
It can be appropriate for pages that should not appear in search, but an accidental directive on a key service page or article can prevent that page from being indexed.
Common causes include development settings that remain active after launch or SEO plugin settings applied to the wrong page.
How to check
- Inspect the page’s meta robots tag.
- Check for an
X-Robots-TagHTTP header where relevant. - Review CMS and SEO plugin settings.
- Confirm that important pages are not unintentionally marked noindex.
- Check that pages intended for indexing are not blocked from crawling in a conflicting way.
Removing a noindex directive does not guarantee indexing, but it removes that particular restriction when it was the cause.
14. Organise Content Into Relevant Topic Clusters
Topic clusters group related articles around a central subject.
For example, an AEO category might have a central guide about answer engine optimisation supported by articles about question research, structured data, internal linking, and AI search visibility.
This structure creates meaningful relationships between pages and gives visitors useful paths to explore a subject in more depth.
To create a cluster:
- Choose a central topic.
- Publish a comprehensive pillar article.
- Identify related questions and subtopics.
- Create focused supporting articles.
- Link the supporting articles to the pillar and to relevant sibling pages.
- Review links when you publish new content.
15. Remember That Crawling, Indexing, and Ranking Are Different
These three processes are related, but they are not the same.
Crawling means a search engine accesses a URL and retrieves information from it.
Indexing means the search engine processes the page and may include it in its searchable index.
Ranking means the search engine determines where an eligible page appears for a particular query.
A page can be crawled without being indexed, and an indexed page is not guaranteed to rank well.
Likewise, making a page easier to crawl does not guarantee that an AI system will cite it in a generated answer.
For AEO, crawlability is one part of the foundation. Content quality, clarity, relevance, technical accessibility, and the way individual answer systems retrieve information also matter.
Website Crawlability Checklist
Use this checklist when reviewing your important website pages.
- Important pages are linked from relevant pages.
- The XML sitemap contains the intended canonical URLs.
- Robots.txt does not accidentally block important content.
- Important pages do not have unintended noindex directives.
- Internal links lead to working destinations.
- Redirects lead directly to relevant pages where possible.
- Canonical tags are consistent with your intended URLs.
- Important content is available in readable HTML.
- Navigation works on desktop and mobile.
- Important pages return appropriate HTTP status codes.
- Google Search Console shows no unresolved critical issues.
- Unnecessary URL variations are managed appropriately.
Frequently Asked Questions
What does it mean to make website content easier to crawl?
It means helping search engine crawlers discover URLs, access their content, and follow relevant links without unnecessary technical obstacles. Internal linking, XML sitemaps, clean site structure, and correct crawl directives all contribute.
Does an XML sitemap guarantee that Google will crawl every page?
No. A sitemap helps Google discover URLs, but it does not guarantee crawling, indexing, or rankings. Pages still need to be accessible and meet the search engine’s criteria for processing and inclusion.
Can a page be crawled but not indexed?
Yes. Search engines may crawl a page but decide not to index it because of duplication, quality, canonicalisation, noindex directives, or other factors.
Does internal linking improve crawlability?
Relevant internal links give crawlers additional ways to discover pages and help them understand relationships between content. They are especially useful for preventing important pages from becoming isolated.
Does crawlability help AEO?
It can provide a useful technical foundation. Search and answer systems need ways to discover and access information, but better crawlability alone does not guarantee that content will be used or cited in AI answers.
How often should I check website crawlability?
Check after major website changes, migrations, URL updates, or technical releases. For active websites, review Search Console and important technical issues regularly, with the frequency based on site size and how often content changes.
Final Thoughts
Making important website content easier to crawl starts with a clear structure and fewer technical obstacles. Help crawlers discover valuable pages through internal links, maintain an accurate sitemap, review crawl directives, fix broken paths, and check important URLs for unexpected errors.
You do not need to make every URL equally important. Focus first on the pages that provide genuine value to your audience and support your website’s goals.
Better crawlability creates a stronger foundation for search visibility, but useful content and proper indexing still matter. Review your most important pages regularly and fix issues before they become larger problems.




Building lightweight web applications with native audio playback is simpler when choosing a midi to ogg sound converter online to format score outputs.